


- Model
- Urdu · English
- CC BY-NC 4.0
Urdu Sukhan ASR
An Urdu speech recognition model that also understands English and speech that switches between Urdu and English. It is fine-tuned from OpenAI’s Whisper large-v3-turbo and makes 39% fewer word errors than that model on seven held-out Urdu test sets. It keeps the turbo model’s speed and size, about half the size of Whisper large-v3.
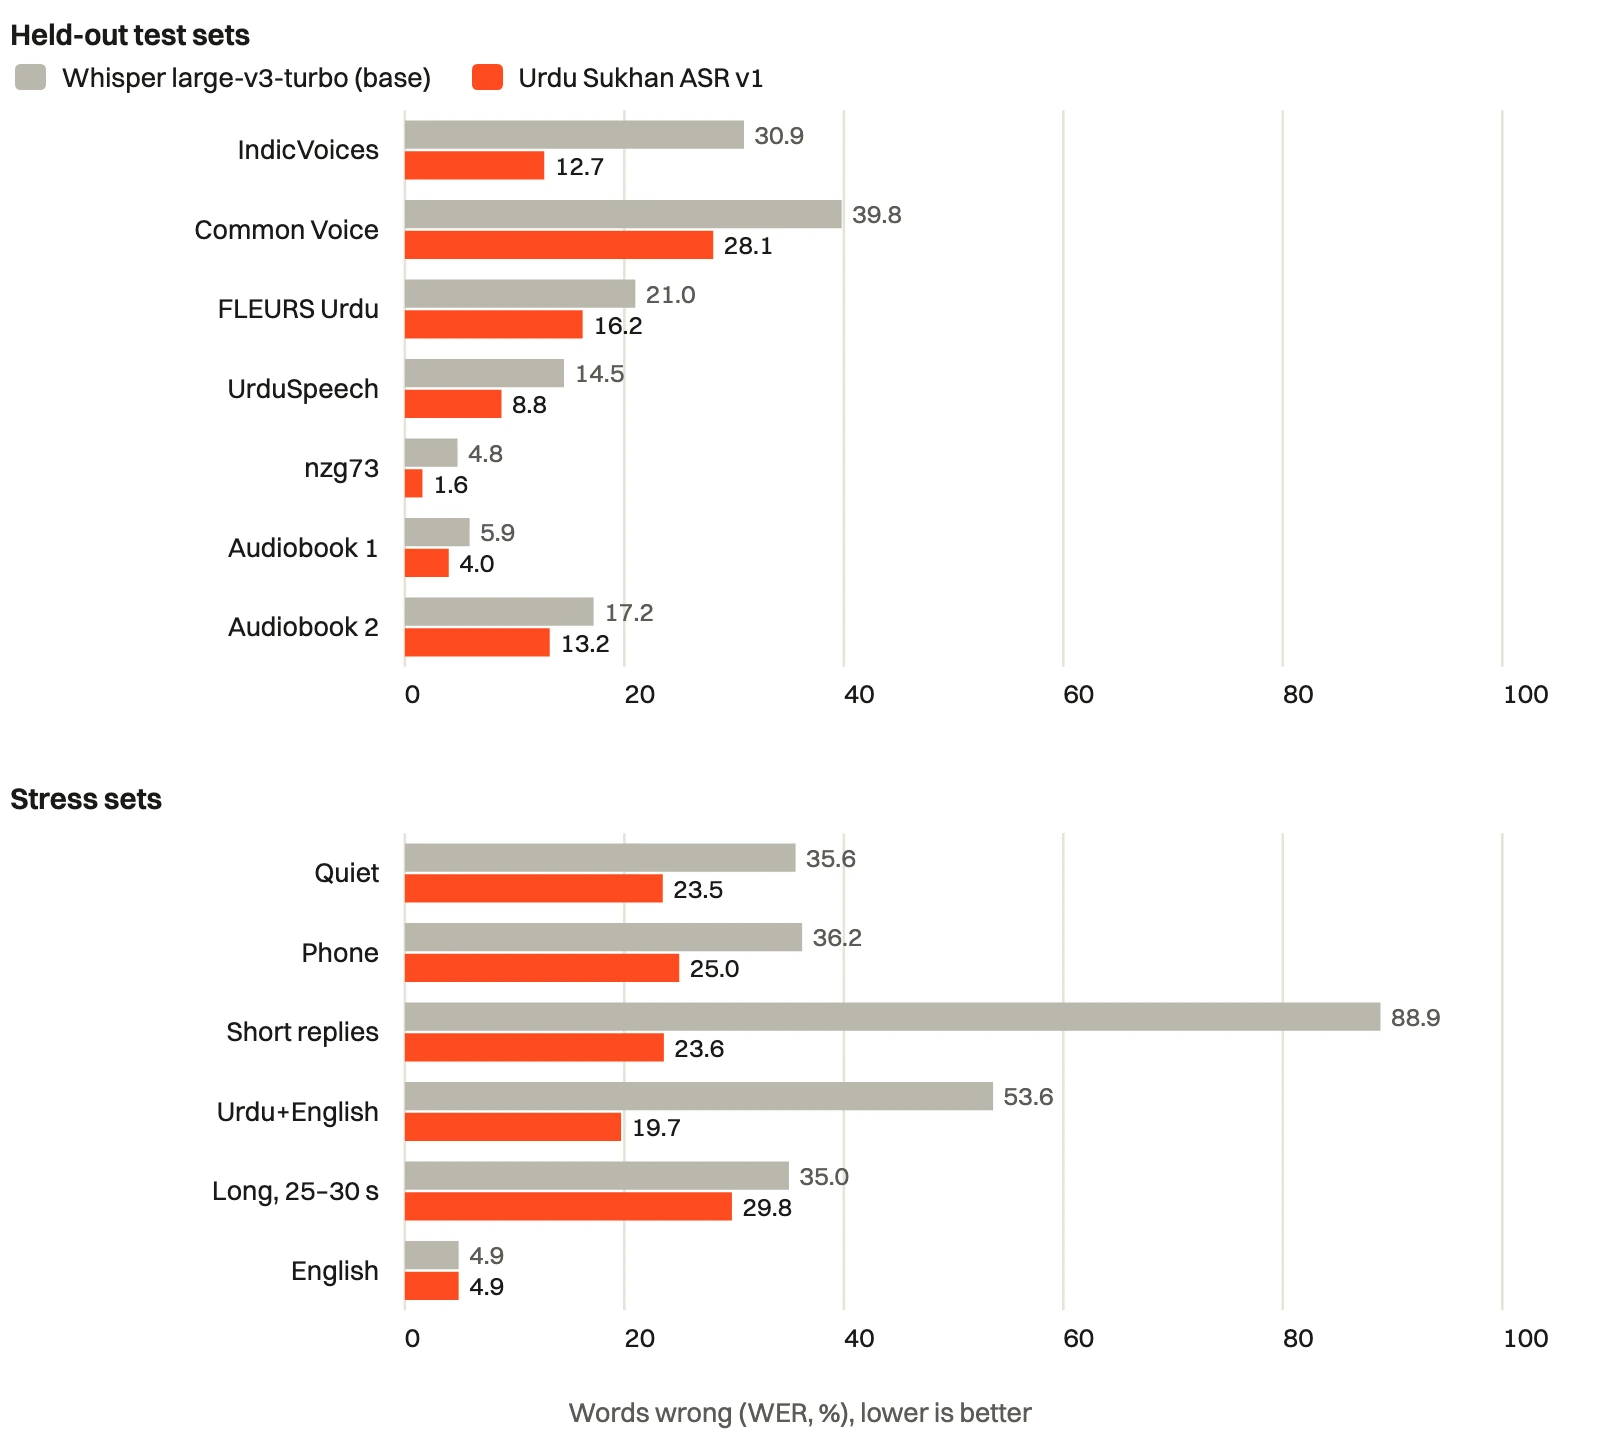
Better Urdu
From 30.9% to 12.7% words wrong on IndicVoices, from 39.8% to 28.1% on Common Voice speakers it never heard, and better on every Urdu test set we have.
English and mixed speech
English stays as accurate as the base model. Clips that switch from Urdu to English fall from 53.6% to 19.7% words wrong, with English words in English letters.
Short replies and silence
One- or two-word replies fall from 88.9% to 23.6% words wrong. With blank suppression off, it writes nothing on silence, noise or music.
Three formats
Transformers (fp16) for Python and GPUs, whisper.cpp (q8_0, q5_0, q4_0) for CPUs and Apple Silicon, and CTranslate2 int8 for faster-whisper.
Half the size of large-v3
809 million parameters, against 1.55 billion for Whisper large-v3, with 32 encoder and 4 decoder layers. One 30-second window takes 1.3 seconds on an Apple M4 GPU.
Open method
The data sources, every training round, including those that failed, and every evaluation are published in our research report and on GitHub.
Results
Words wrong (WER, %) after the same normalisation for both models, with greedy decoding in Hugging Face Transformers. None of these sets was used in training.
| Test set | Whisper large-v3-turbo | Urdu Sukhan ASR v1 |
|---|---|---|
| IndicVoices Urdu validation | 30.9 | 12.7 |
| Common Voice, unseen speakers | 39.8 | 28.1 |
| FLEURS Urdu test | 21.0 | 16.2 |
| UrduSpeech test split | 14.5 | 8.8 |
| nzg73, held-out clips | 4.8 | 1.6 |
| Audiobook 1, held-out chapters | 5.9 | 4.0 |
| Audiobook 2, held-out chapter | 17.2 | 13.2 |
| Stress: one- or two-word replies | 88.9 | 23.6 |
| Stress: Urdu then English in one clip | 53.6 | 19.7 |
| Stress: English (FLEURS) | 4.9 | 4.9 |
The test sets we can share, 808 clips (about 96 minutes) from the Common Voice and FLEURS Urdu test sets and eight stress sets, are on Hugging Face on request. Get IndicVoices, UrduSpeech and nzg73 from their publishers.
Compared with Whisper large-v3
Urdu Sukhan ASR has the layout of Whisper large-v3-turbo: the same 32-layer encoder as Whisper large-v3 and a 4-layer decoder instead of 32.
| Whisper large-v3 | Urdu Sukhan ASR (turbo layout) | |
|---|---|---|
| Parameters | 1,550 M | 809 M |
| Encoder / decoder layers | 32 / 32 | 32 / 4 |
| whisper.cpp file, fp16 | 3,095 MB | 1,625 MB |
| whisper.cpp file, q5_0 | 1,081 MB | 574 MB |
| GPU memory (OpenAI) | about 10 GB | about 6 GB |
| Relative speed (OpenAI: English, A100) | 1× | about 8× |
OpenAI’s speed figure comes from the smaller decoder. On a CPU in whisper.cpp, the encoder, which both models share in size, does about 95% of the work, so the gain there is much smaller. We have not timed or scored Whisper large-v3 ourselves.
Sources:
Use it
Try it in Colab, without installing
Our Colab notebook runs the model in your own Google Colab session, on a free GPU or the CPU: record from the microphone, upload a file or try the example clips, with the recommended settings built in. It needs an approved access request and a free Google account. Your audio goes to your Colab session on Google’s servers, never to Loudness.ai.
whisper.cpp (command line)
git clone https://github.com/Loudness-ai/urdu-sukhan-asr.git
cd urdu-sukhan-asr
bash examples/whisper_cpp.sh speech.wav
faster-whisper (Python)
python -m pip install faster-whisper==1.2.1 ctranslate2==4.8.3 huggingface_hub==2.2.0 soundfile==0.14.0 soxr==1.1.0
python examples/transcribe_faster_whisper.py speech.wav
Transformers (Python)
python -m pip install -r examples/requirements.txt
python examples/transcribe_transformers.py speech.wav
The model files are shared on request, so first request access on Hugging Face and log in with hf auth login. Each command then runs a tested script from the examples folder of the GitHub repository. The installation guide covers each format step by step, with the settings and common problems:
Recommended settings
- Set the language (
uroren) when you know it. Auto-detection runs the encoder an extra time in whisper.cpp. - Turn off blank suppression so that silence returns nothing: the
-nsbswitch of the patched whisper-cli that our script builds, orsuppress_blank = falsein the whisper.cpp library. - Decode with beam 5, without timestamps and without carried-over context.
- Run a voice activity detector first and cut long files at pauses into pieces of up to about 25 seconds. The detector can drop faint speech, such as quiet English after Urdu, so turn it off if words go missing (
VAD=0or--no-vadin our scripts). - In whisper.cpp, q8_0 is the best format on Apple Silicon and q4_0 the fastest on x86 servers.
- On a CPU, use whisper.cpp or faster-whisper: Transformers runs about ten times slower than real time there.
Limitations
Read these before relying on the model.
- Names are its weakest point. The test chapter of our second audiobook has 23 name occurrences: Urdu Sukhan ASR spelled 11 right, the base model 4. Names it rarely heard in training come out as similar common words, for example عمیر (Umair) as امیر (“rich”) and تانیا (Tania) as دانیا. A prompt listing the expected names raised the count from 12 to 17 of 23 in whisper.cpp. FLEURS news, full of foreign names, is where it improves least. When names matter (people, places, brands), give them in a prompt and check them by hand.
- Word spacing and spelling. Words are sometimes joined or split (آنندوہار for آنند وہار), and spelling follows our house style, which can differ from yours.
- No punctuation. Transcripts come without punctuation, like the training text.
- Very faint English after Urdu can come out in Urdu letters or repeat a word.
- Narrator-specific pronunciations, for example a dropped ھ (پھر heard as پر), are sometimes written as pronounced.
- Silence. Without the blank setting above, it writes a word such as اچھا on silence, as every Whisper model does.
- Accents and settings. IndicVoices is mostly Indian Urdu, the Common Voice test has few women, and we have no test of spontaneous phone conversations between Pakistani speakers. Our test sets are small (20 to 300 clips) and we report no confidence intervals.
- Speed on CPUs. Every clip pays for a full 30-second window, so short live clips are slower than real time on small CPUs.
- Not measured. We have not scored or timed Whisper large-v3, measured memory use, or run the model on a phone.
Next version
What we plan to change for the next model, each from a problem this one showed:
| Problem in v1 | Plan for the next model |
|---|---|
| Names: 11 of 23 right in our test chapter; rare names become common words | More name-rich training speech (news, interviews, stories with many characters), a larger test set of names, and name prompts in the examples and test page |
| Faint training speech taught the model to hear words in hiss | Set every clip to a normal level before augmenting it |
| One word on silence unless an empty result is allowed | Encode empty transcripts without a space, so the model can stop with default settings |
| Stress-test noise and music were heard in training | Keep test noise and music out of augmentation |
| Joined or split words | Check training transcripts for word spacing and count spacing errors separately |
| Every clip pays for a 30-second window on CPUs | Fine-tune for shorter audio windows; train a smaller, faster student on more teacher-transcribed audio (our 16-layer student was 1.9× faster in the encoder but 0.5–5.4 points less accurate, so it is not released) |
| No iPhone build (the Core ML encoder lost precision) | A precise on-device build for iPhone |
| Settings we have not tested | Pakistani conversational and phone speech, more women speakers, larger test sets with confidence intervals, memory and phone measurements, and a direct comparison with Whisper large-v3 |
Data and credits
Trained on about 110 hours: IndicVoices and the Urdu part of Rasa by AI4Bharat, Mozilla Common Voice, Google FLEURS, the dataset of Muhammad Noman – nzg73 under its own licence, UAT audio only (transcribed by our own model; no public licence; used by agreement with its developers), MUSAN noise and music, and two audiobooks read by two narrators, with transcripts proofread by Asad Shehzad. The research report lists every source and its terms.
Research report Example audio on Hugging FaceTest sets on Hugging Face
Runs where you run it
The model runs on your computer, your server or in your app, and audio is never sent to Loudness.ai. Downloading the model needs a Hugging Face account with approved access; running it needs no account or key.
Licence
Urdu Sukhan ASR is released under the CC BY-NC 4.0 licence: free for non-commercial use, with credit. The model files are shared on request: ask for access on Hugging Face, and we approve each request by hand. For commercial use, contact us.
Prefer the browser?
Clean a recording before you transcribe it, free online:
Audio EnhancerEcho RemoverExtract Audio from VideoSilence Remover
Cite
Shehzad, A. (2026). Urdu Sukhan ASR: Accurate Urdu Speech Recognition at Half the Size of Whisper large-v3. Technical report LA-RB-2026-004, Loudness.ai. DOI: 10.5281/zenodo.23518703.
BibTeX and RIS files are on the research report page:
Links
Hugging FaceGitHubExample audio on Hugging FaceTest sets on Hugging Face Try it in Colab
 Installation guideResearch reportAI Noise Remover SDKloudness-ttsAll developer guides